querying data that won’t fit in memory
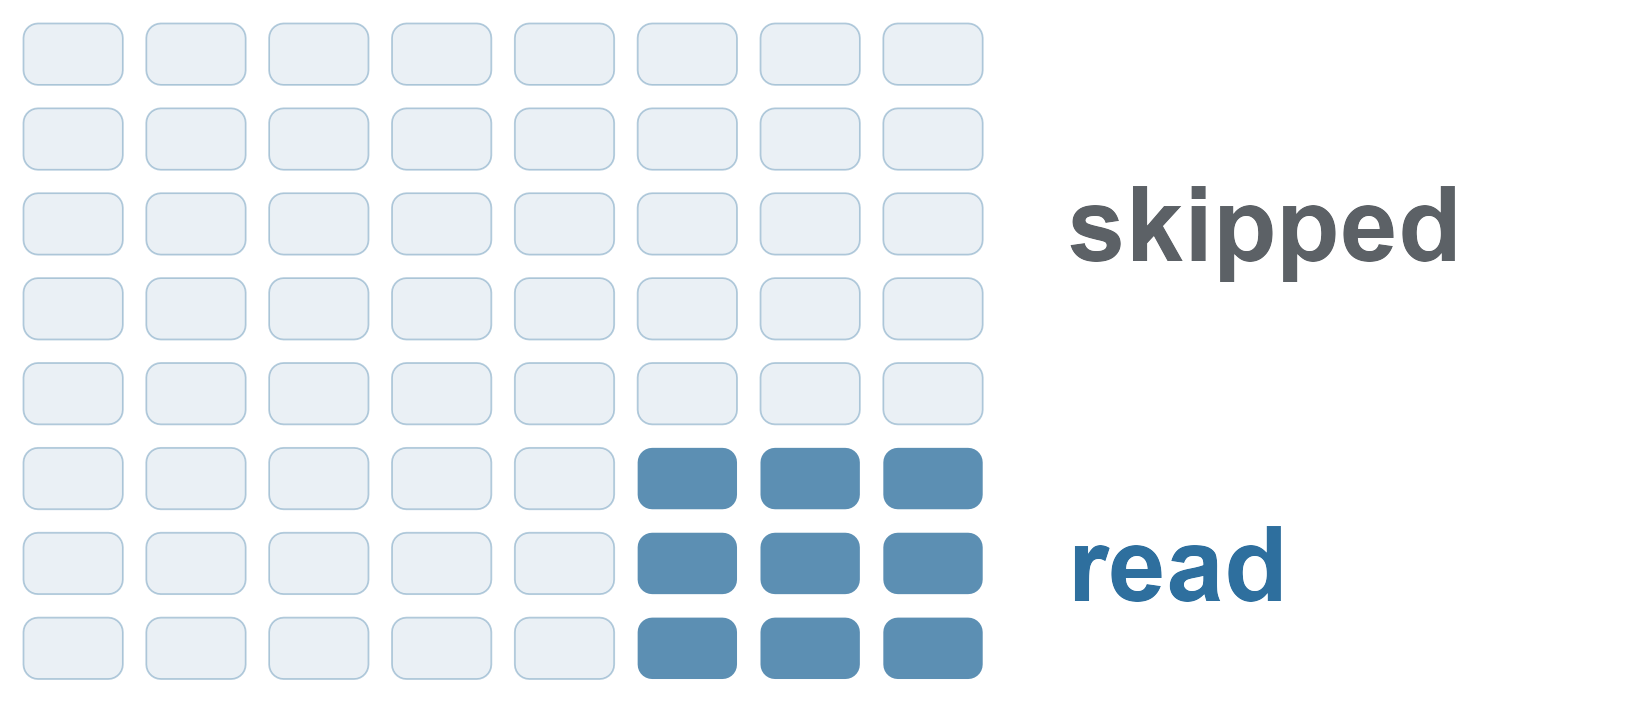
vectra runs dplyr-style queries on files that are too large to load into memory: multi-gigabyte CSV and Parquet files, SQLite databases, GeoTIFF rasters and its own .vtr columnar format.
The verbs build a lazy query plan, and collect() executes it in a C11 engine that pulls one row group (a block of rows that is stored and decoded together) through the plan at a time. Peak memory therefore stays bounded however large the file is. Row groups whose stored minimum and maximum rule out a filter are skipped without being read. You decide what comes back into R: a result small enough to fit, or a stream that feeds a model fit or a file.
vectra supports:
-
Larger-than-memory queries.
filter(),mutate(),group_by()withsummarise(), joins and window functions stream through the engine, and sorts, joins and aggregations spill to disk when they reach a memory budget (Working with Large Data). -
Several file formats.
.vtr, Parquet, CSV, SQLite and GeoTIFF open into the same lazy query nodes, so one pipeline runs against any of them (Format Backends). - Skipping what a query does not need. The scan reads only the columns a query references, and row group statistics and optional hash indexes skip row groups that cannot match a filter (Indexing and Query Optimization).
-
Fuzzy matching and geometry in expressions. The string distances
levenshtein(),dl_dist()andjaro_winkler()and thest_*geometry functions evaluate insidefilter()andmutate(), in C, with no round trip to R per row (String Operations and Fuzzy Matching, Geometry functions in expressions). -
Spatial and raster data. Spatial joins, overlay, dissolve, routing on line networks, and raster operations such as
zonal(),focal()andterrain()process one batch or tile at a time (Out-of-core GIS with vectra). -
Model fits on out-of-core data.
collect_chunked()folds a function over a query one batch at a time, andchunk_feeder()andoffload()feedbiglm::bigglm()(Offloading: streaming, monoids, and out-of-core fits). - No system libraries. The C engine and its codecs are compiled from the package sources. The only compiled R dependency is libgeos, which supplies GEOS (Geometry Engine, Open Source) for the spatial functions.
The test suite checks the optimizer’s rewrites, such as column pruning and predicate pushdown, against base R results, and sanitizer builds (AddressSanitizer and UndefinedBehaviorSanitizer) run in continuous integration.
Installation
install.packages("vectra")            # CRAN

install.packages("pak")               # development version
pak::pak("gcol33/vectra")
The development version compiles C code, which needs Rtools on Windows, the Xcode command line tools on macOS, or r-base-dev on Linux.
Usage
A vectra query has three parts. A source function such as tbl() opens a file, verbs describe the query, and collect() runs it. The verbs only extend the plan, so nothing is read until collect().
library(vectra)
#>
#> Attaching package: 'vectra'
#> The following object is masked from 'package:stats':
#>
#>     filter
#> The following object is masked from 'package:graphics':
#>
#>     grid

f <- tempfile(fileext = ".vtr")
write_vtr(mtcars, f)

tbl(f) |>
  filter(cyl == 4) |>
  group_by(gear) |>
  summarise(avg_mpg = mean(mpg), n = n()) |>
  collect()
#>   gear avg_mpg n
#> 1    3  21.500 1
#> 2    4  26.925 8
#> 3    5  28.200 2
write_vtr() converts a data frame to the .vtr format. Converting a large CSV once makes repeated queries cheaper, because .vtr stores the row group statistics that the scan uses to skip data.
The verbs follow dplyr: filter(), select(), mutate(), group_by() and summarise(), all the joins from left_join() to cross_join() plus fuzzy_join(), arrange(), the slice_*() family and window functions such as row_number(), rank(), lag() and cumsum(). select(), rename(), relocate() and across() accept the tidyselect helpers. The function reference lists every verb and expression.
One pipeline for several file formats
Each source function opens its format into the same lazy query nodes.
# A folder of Parquet files as one table
tbl_parquet("occurrence.parquet/") |>
  filter(countrycode == "AT", year >= 2000) |>
  count(species) |>
  collect()

# A GeoTIFF raster as tidy data
tbl_tiff("worldclim_bio1.tif") |>
  filter(band1 > 0) |>
  mutate(temp_c = band1 / 10) |>
  collect()

# A SQLite database, without DBI
tbl_sqlite("survey.db", "responses") |>
  filter(year == 2025) |>
  left_join(tbl_sqlite("survey.db", "sites"), by = "site_id") |>
  collect()
Reading the query plan
explain() prints the optimized plan, including the columns and row groups that the scan skips.
Fuzzy matching
String distance functions run inside the engine, so a fuzzy filter costs no round trip to R per row.
Spatial data
Geometry travels through the engine as WKB (well-known binary) in an ordinary column, so the spatial verbs stream one batch at a time like the rest. This call tags a stream of points with the polygon each one falls in, holding the polygons and one batch in memory.
library(sf)

tbl("gps_pings.vtr") |>
  spatial_join(zones_sf, join = st_intersects) |>
  count(zone_id) |>
  collect()
The spatial toolbox also covers st_* functions inside filter() and mutate(), vector-raster bridges (rasterize(), polygonize(), contours()), planar overlay and coverage cleaning (spatial_overlay(), spatial_dissolve(), spatial_eliminate()) and routing on a line network (spatial_network(), spatial_route(), spatial_service_area()). Geometry operations run on GEOS through libgeos. sf is needed for vector file input and output and for reprojection. Out-of-core GIS with vectra is the place to start.
Star schemas
A star schema registers dimension tables once. lookup() then pulls columns from any of them, builds the joins and reports unmatched keys.
Incremental updates
append_vtr() adds new rows to a .vtr file as new row groups without rewriting the existing ones, and diff_vtr() compares two snapshots by key.
append_vtr(new_rows_df, "data.vtr")

d <- diff_vtr("snapshot_old.vtr", "snapshot_new.vtr", key_col = "id")
collect(d$added)   # rows present in new but not old
d$deleted          # key values present in old but not new
Streaming results into a model fit
collect_chunked() folds a function over a query one batch at a time. It holds a single batch and the accumulator, so a result larger than memory reduces to a small summary in one pass. This example accumulates the cross-products behind an exact linear fit.
acc <- tbl("survey.vtr") |>
  select(mpg, wt, hp) |>
  collect_chunked(
    function(acc, chunk) {
      X <- cbind(1, chunk$wt, chunk$hp)
      list(XtX = acc$XtX + crossprod(X),
           Xty = acc$Xty + crossprod(X, chunk$mpg))
    },
    .init = list(XtX = matrix(0, 3, 3), Xty = matrix(0, 3, 1))
  )
solve(acc$XtX, acc$Xty)
Models that re-read the data on every iteration use chunk_feeder(), which exposes a query as a resettable generator for biglm::bigglm(). offload() writes a prepared query to disk once and streams it back, and with a by key it splits the query into per-key shards that each fit in memory, so group_map() can run any R function on each shard. Offloading: streaming, monoids, and out-of-core fits covers both.
Documentation
Start with Getting Started with vectra, which takes one query from a file to a collected result.
Engine:
- vectra Engine Reference: the engine’s verbs and expressions.
- Format Backends: opening and writing each file format.
- Joins: the join verbs.
- Star Schemas and Lookup: registering dimension tables and pulling columns from them.
- String Operations and Fuzzy Matching: string functions and distance joins.
- Indexing and Query Optimization: hash indexes and the optimizer’s rewrites.
- Working with Large Data: keeping memory bounded on large inputs.
- Offloading: streaming, monoids, and out-of-core fits: model fits on data larger than memory.
Spatial:
- Out-of-core GIS with vectra: vector and raster operations on large layers.
- Streaming spatial operations: the streaming spatial verbs.
-
Geometry functions in expressions:
st_*functions insidefilter()andmutate(). - Coverage and topology: overlay and coverage cleaning.
- Network analysis: routing and service areas on line networks.
- Species Distribution Models: a model fit on out-of-core occurrence data.
The function reference lists every exported function, grouped by job.
Getting help
Questions and bug reports go to the GitHub issue tracker. A bug report with a small reproducible example (a reprex) is the quickest to fix.
Support
“Software is like sex: it’s better when it’s free.” — Linus Torvalds
I’m a PhD student who builds R packages in my free time because I believe good tools should be free and open. I started these projects for my own work and figured others might find them useful too.
If this package saved you some time, buying me a coffee is a nice way to say thanks. It helps with my coffee addiction.
Acknowledgements
vectra vendors the zstd decoder and xxHash by Yann Collet and Meta Platforms, Inc., and miniz by Rich Geldreich, Martin Raiber and contributors. tdc, the compression library written for vectra, is vendored into the package.