Pushforwards and Pullbacks
The Die and the Question
Roll a die. You get a 4.
Now I ask: “Is it even?”
Asking the question moved the randomness. It started in a space of six faces, then traveled to a space of two labels: odd and even. The uniform distribution on faces became a fair coin on parity.
This movement has a direction. Parity is something we impose after the roll, and once we ask the question, probability flows forward through it, landing in a simpler space.
What if we reverse direction? Suppose I define a reward: $1 if even, $0 if odd. That function lives in parity-space. But to compute your expected winnings, you need to pull it back to die-space, where the probability lives.
These are the two directions of mathematical transport: measures push forward through a map, while functions pull back against it.
The same pattern reaches far beyond dice. It is the grammar by which mathematics moves structure from one space to another.
See It Happen
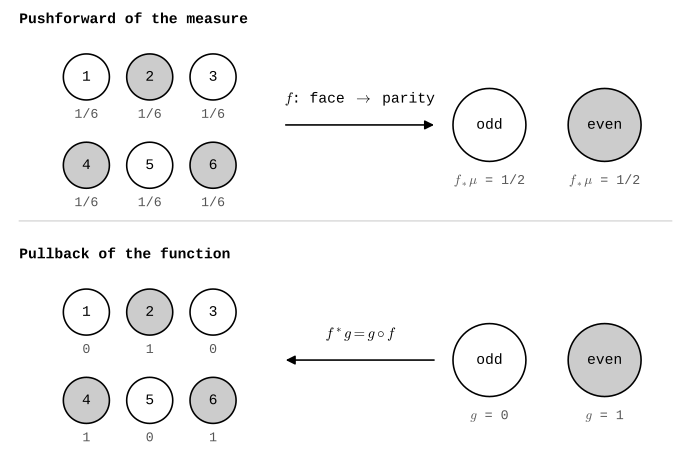
The measure moves forward through $f$: $P({\text{odd}}) = P({1,3,5}) = 1/2$, and likewise for even. The reward $g$ moves backward: $g(\text{even}) = 1$, $g(\text{odd}) = 0$ becomes the indicator of ${2,4,6}$ on the die.
Why Two Directions?
The two directions appeared in geometry long before probability theory existed. When you stretch or bend a surface and map it onto another, certain quantities move with the map, while others move against it.
Tangent vectors push forward. If you have a direction at a point and you stretch the surface, the direction stretches along with it.
Functions pull back. If you have a function defined on the target surface (say, temperature), you can read its values on the source by composing with the map.
This duality appeared again in physics (contravariant vs. covariant tensors) and eventually in probability.
Whenever you have a map between spaces, two operations arise, one following the map and one opposing it.
The Formal Definitions
Fix a measurable map $f: X \to Y$.
Pushforward of measures. Let $\mu$ be a measure on $X$. Define a measure on $Y$ by:
\[(f_{*}\mu)(B) \;=\; \mu\!\bigl(f^{-1}(B)\bigr) \qquad \text{for } B \subseteq Y \text{ measurable}.\]This is covariant: $(g \circ f)* = g* \circ f_*$.
Pullback of functions. Let $g: Y \to \mathbb{R}$ be measurable. Define a function on $X$ by:
\[f^{*}g \;=\; g \circ f : X \to \mathbb{R}.\]This is contravariant: $(g \circ f)^* = f^* \circ g^*$.
The notation reflects the direction. Subscript $$ for pushforward (following the arrow). Superscript $$ for pullback (against the arrow).
Why Inverse Images?
A natural question: why define pushforward using inverse images? Why not just push sets forward directly?
Measure theory demands additivity. If $A_1, A_2, \dots$ are disjoint sets in $X$, their direct images $f(A_1), f(A_2), \dots$ need not be disjoint in $Y$. Two different points in $X$ might land on the same point in $Y$.
But inverse images behave perfectly:
\[f^{-1}(B_1 \cup B_2) = f^{-1}(B_1) \cup f^{-1}(B_2), \qquad f^{-1}(B^c) = f^{-1}(B)^c.\]Inverse images preserve the set operations that σ-algebras need. Pushforward uses inverse images even though the measure moves “forward.”
The Adjunction: Where the Two Directions Meet
The integral ties pushforward and pullback together.
For a measure $\mu$ on $X$ and a function $g$ on $Y$:
\[\int_{Y} g(y)\, d(f_{*}\mu)(y) \;=\; \int_{X} (g \circ f)(x)\, d\mu(x).\]On the left, the measure moves forward to $Y$, where $g$ lives. On the right, the function moves backward to $X$, where $\mu$ lives. Both integrals compute the same number.
This is the change-of-variables formula. In the language of category theory it is an adjunction. The integral defines a pairing between functions and measures, and pushforward/pullback preserve that pairing.
Written symbolically: $f^* \dashv f_*$. Pullback is left adjoint to pushforward.
Category Theory: The General Framework
The pattern of pushforwards and pullbacks is captured by category theory’s language of functors.
A category consists of:
- Objects: the spaces (sets, measurable spaces, manifolds)
- Morphisms: the maps between them
- Composition: maps can be chained, and identity maps exist
A functor assigns objects to objects and morphisms to morphisms, respecting composition.
- Covariant functors preserve direction: $F(g \circ f) = F(g) \circ F(f)$
- Contravariant functors reverse direction: $F(g \circ f) = F(f) \circ F(g)$
In probability, sending each space $X$ to its measures and each map $f$ to $f_$ gives a covariant functor; sending each space to its observables and each map to $f^$ gives a contravariant one.
The integral formula is the adjunction that ties them together.
The same pattern appears in topology (homology vs. cohomology), in algebra (extension vs. restriction of scalars), in logic (existential vs. universal quantifiers).
Back to the Die
Let’s make this concrete with the full calculation.
The spaces:
\[\Omega = \{1, 2, 3, 4, 5, 6\}, \qquad P(\{i\}) = \tfrac{1}{6}.\] \[Y = \{\text{odd}, \text{even}\}, \qquad f(i) = \text{parity of } i.\]Pushforward of $P$:
\[f_*P(\{\text{odd}\}) = P(\{1, 3, 5\}) = \tfrac{1}{2}, \qquad f_*P(\{\text{even}\}) = P(\{2, 4, 6\}) = \tfrac{1}{2}.\]The uniform distribution on faces becomes the fair coin on parity.
Pullback of a reward function:
Define $g: Y \to \mathbb{R}$ by $g(\text{even}) = 1$, $g(\text{odd}) = 0$.
\[f^*g = g \circ f : \Omega \to \mathbb{R}\]is the indicator function of ${2, 4, 6}$.
The adjunction in action:
\[\int_Y g \, d(f_*P) = 1 \cdot \tfrac{1}{2} + 0 \cdot \tfrac{1}{2} = \tfrac{1}{2}.\] \[\int_\Omega f^*g \, dP = \sum_{i \in \{2,4,6\}} \tfrac{1}{6} = \tfrac{1}{2}.\]Both integrals agree. The expected reward is 1/2, computed either by pushing the measure forward or pulling the function back.
Distributions Are Pushforwards
A random variable is a measurable map $X: \Omega \to \mathbb{R}$. Its distribution is:
\[P_X(B) = P(X^{-1}(B)) = (X_* P)(B).\]The distribution is the pushforward of the base probability through the random variable.
Marginal distributions follow the same pattern. For a joint distribution on $X \times Y$, the marginal on $X$ is the pushforward along the projection $\pi_X$:
\[(\pi_X)_* \mu (A) = \mu(A \times Y).\]Distributions, marginals and transformations are all pushforwards of the same base measure through different maps.
What About Conditioning?
Conditioning describes how beliefs update when information arrives. Given an event $B$ with $P(B) > 0$:
\[P(A \mid B) = \frac{P(A \cap B)}{P(B)}.\]This is not transport along a map. It’s restriction to a slice, followed by renormalization.
Pushforwards move probability between spaces. Conditioning reshapes probability within a single space.
(Disintegration theory can encode conditioning using pushforwards, but the naive picture of “push through a map” doesn’t capture what conditioning does.)
From Statistics to Neural Networks
The abstract pattern reappears wherever models transform probability.
Bayesian inference. The entire posterior over parameters $\boldsymbol{\beta}$ is pushed through the model:
\[p(y^* \mid \text{data}) = \int p(y^* \mid \boldsymbol{\beta}) \, p(\boldsymbol{\beta} \mid \text{data}) \, d\boldsymbol{\beta}.\]This integral is a pushforward. The posterior on parameters becomes a predictive distribution on outcomes.
Generative models. A neural network maps a simple distribution (Gaussian noise in latent space) to a complex distribution (images, text, audio). The generator is a map $G: Z \to X$, and the generated distribution is:
\[p_X = G_* p_Z.\]Every image produced by a diffusion model or GAN is a sample from a pushforward.
Normalizing flows. These models make the pushforward explicit. They construct invertible maps with tractable Jacobians, so the density of the pushforward can be computed exactly:
\[p_X(x) = p_Z(G^{-1}(x)) \cdot |\det \nabla G^{-1}(x)|.\]The Jacobian determinant records how the pushforward stretches volume.
The Grammar of Structure
Gauss and Riemann studied how curvature behaves under maps between surfaces: pullbacks carrying differential forms, pushforwards carrying tangent vectors, the Jacobian determinant holding them together. Category theory later gave this pattern a formal home with functors and adjunctions.
The same structure appears in machine learning. Monte Carlo methods push simple randomness into complex simulations. Variational inference pulls expectations back through intractable models. Generative AI pushes latent noise into images and text. In each case, a single map gives rise to two operations, one moving mass forward, the other moving observables back, and integration holds them in balance.