Why Dividing Two Random Numbers Reveals π
Where More Data Doesn’t Mean More Certainty
Take two random numbers and divide them.
Do it again. And again.
Now average the results.
Does the number settle down?
No matter how many times you repeat the experiment, the mean refuses to converge. And hidden inside that chaos is something stranger still.
Collect the slopes, count how many land in a narrow strip around horizontal, then scale by the strip’s width. A circle’s number quietly emerges.
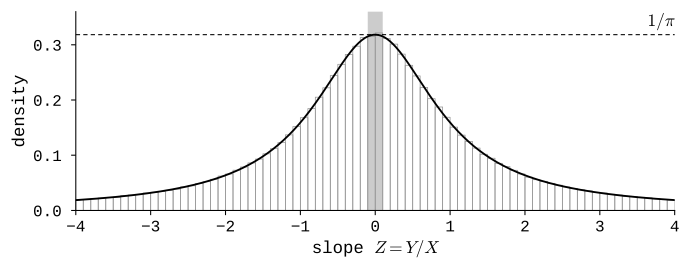
The histogram holds a million slopes, each the ratio of two independent standard Gaussians. The shaded strip is the band $\lvert Z\rvert \le h$ with $h = 0.1$. Dividing the band’s total width $2h$ by the fraction of slopes inside it gives 3.143.
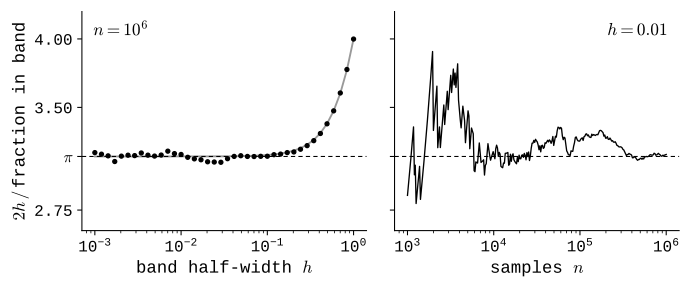
The left panel repeats the calculation for bands from $h = 0.001$ to $h = 1$ with the same million slopes. Wide bands overshoot: the estimate is 3.227 at $h = 0.3$ and 3.999 at $h = 1$, following the gray curve $\pi h/\arctan h$. Narrow bands catch few slopes, and the estimate scatters around 3.14. The right panel fixes $h = 0.01$ and follows the estimate as samples accumulate: it swings between 2.80 and 3.91 over the first ten thousand samples and ends at 3.156 after a million.
Why π? Why does averaging fail, even with mountains of data?
To find out, we need to go back to Gauss, to Cauchy, and to a curve first drawn in 1748.
How a Simple Curve Defied Gauss
Gauss believed in certainty through numbers. His bell curve promised that measurement errors were well-behaved: they came from many small independent causes, variance was finite, and averages converged to the truth. The law of large numbers guaranteed stability, and the central limit theorem explained the bell shape. With more data, you approached certainty.
In 1853, before the Académie des Sciences in Paris, Cauchy presented a rival law of errors in which variance was infinite and averages refused to settle. Joseph Bienaymé rose to defend Gauss, warning that least squares collapsed without finite variance. Cauchy insisted that mathematics itself admitted such laws, and that in their presence the Gaussian guarantees failed.
The curve Cauchy used had been introduced a century earlier, in 1748, by Maria Gaetana Agnesi in her Instituzioni Analitiche. Agnesi worked in the geometric analytic tradition of the 18th century, when curves were defined by geometric constructions and explored with the new tools of calculus.
Agnesi’s Instituzioni was written in Italian rather than Latin, aimed at students, designed to systematize analysis in a clear, accessible way. Her versiera came from a simple construction: a circle, a fixed point on its diameter, a rotating line, and a point tracing where it cut an axis. The resulting curve was bounded, symmetric, and easy to draw. Its equation:
\[y=\frac{a^3}{x^2+a^2}\]For $a=1$:
\[y=\frac{1}{1+x^2}\]Its integral is the arctangent, which ties the curve back to circle geometry. Later, through mistranslation, it acquired the odd name “Witch of Agnesi.”
Normalized to unit area, the same curve is Cauchy’s law of errors:
\[f(x)=\frac{1}{\pi(1+x^2)}\]The total area under the curve is one:
\[\frac{1}{\pi}\int_{-\infty}^{\infty}\frac{dx}{1+x^2} =\frac{1}{\pi}\Big(\tfrac{\pi}{2}-(-\tfrac{\pi}{2})\Big)=1\]Its tails decay like $1/x^2$, far more slowly than the Gaussian’s, and the mean diverges. By symmetry the principal value is zero, but the absolute expectation:
\[\int_{-\infty}^{\infty} \lvert x\rvert f(x)\,dx =\frac{2}{\pi}\int_{0}^{\infty}\frac{x}{1+x^2}\,dx =\frac{1}{\pi}\Big[\ln(1+x^2)\Big]_{0}^{\infty}\]is infinite. The variance fares no better:
\[\int_{-\infty}^{\infty} x^2 f(x)\,dx =\frac{2}{\pi}\int_{0}^{\infty}\left(1-\frac{1}{1+x^2}\right)\!dx\]Truncating at $R$ gives $\frac{2}{\pi}(R-\arctan R)$, which grows without bound.
Here was a legitimate law of errors with no mean and no variance. Averages of such errors wander instead of converging, the central limit theorem does not apply, and the method of least squares loses its justification.
Only later did mathematicians discover a simpler route to the same law: take two independent Gaussians, divide one by the other, and Cauchy’s distribution reappears.
Geometry of the Slope
Start with the pair $(X,Y)$ of independent standard Gaussians. Their joint density:
\[g(x,y) = \frac{1}{2\pi} e^{-\tfrac{1}{2}(x^2+y^2)}\]depends only on the radius $r=\sqrt{x^2+y^2}$, so rotating the plane leaves the Gaussian cloud unchanged: no direction is special.
In polar coordinates $(r,\theta)$ with $x=r\cos\theta$ and $y=r\sin\theta$, the density becomes:
\[g(r,\theta)\,r\,dr\,d\theta = \frac{1}{2\pi} e^{-r^2/2}\, r\,dr\,d\theta\]The angle $\theta$ is uniform on $(-\pi,\pi)$. Slopes $y/x$ correspond to angles in $(-\tfrac{\pi}{2},\tfrac{\pi}{2})$, so:
\[\theta \sim \text{Uniform}\!\left(-\tfrac{\pi}{2}, \tfrac{\pi}{2}\right)\]Now:
\[Z = \frac{Y}{X} = \tan\theta\]The slope of the line through the origin and the random point $(X,Y)$. Picking a Gaussian ratio is the same as picking a random direction and asking how steep it is.
Because $\theta$ is uniform, the density of $Z$ comes from the change of variables formula:
\[f_Z(z) = \frac{1}{\pi}\cdot \frac{1}{1+z^2}\]As $\theta$ approaches $\pm\tfrac{\pi}{2}$, the slope shoots to infinity. Directions near vertical have the same chance as any other angle, so extreme ratios appear regularly, and each one pulls the running average far from where it was.
Algebraic Proof
Cauchy himself never used this geometric shortcut; probability theory in 1853 did not yet have the language of random variables and transformations. His argument stayed analytic. The ratio-of-Gaussians view came later, in the early 20th century, as statisticians formalized distribution theory.
Formally, let $X$ and $Y$ be independent standard Gaussians and set $Z=Y/X$. The density is obtained by integrating out $X$:
\[f_Z(z) = \int_{-\infty}^\infty f_{X,Y}(x,zx)\,|x|\,dx\]with $f_{X,Y}(x,y) = \tfrac{1}{2\pi}\exp[-\tfrac{1}{2}(x^2+y^2)]$. Substituting $y=zx$:
\[f_Z(z) = \int_{-\infty}^\infty \frac{1}{2\pi} \exp\!\left(-\tfrac{1}{2}(1+z^2)x^2\right) |x|\,dx\]Since the integrand is even:
\[f_Z(z) = \frac{1}{\pi}\int_{0}^\infty x \exp\!\left(-\tfrac{1}{2}(1+z^2)x^2\right) dx\]Let $u=\tfrac{1}{2}(1+z^2)x^2$:
\[f_Z(z) = \frac{1}{\pi}\int_{0}^\infty e^{-u}\,\frac{du}{1+z^2} = \frac{1}{\pi(1+z^2)}\]A Law Without an Average
The density we derived:
\[f(z) = \frac{1}{\pi(1+z^2)}\]is the Cauchy distribution. Its height at zero:
\[f(0) = \frac{1}{\pi}\]That is exactly the fraction of slopes you expect to land inside a narrow band, once rescaled by the band’s width. Rearranging:
\[\pi = \frac{2h}{\Pr(|Z|\le h)} \quad \text{for small } h\]This is the value the estimates in the figures approach. The π comes from the length of the angle interval: $\theta=\arctan(Y/X)$ is uniform on $(-\tfrac{\pi}{2},\tfrac{\pi}{2})$, an interval of length π, so each slice of angle of width $\varepsilon$ carries probability $\varepsilon/\pi$. Push that uniform angle through the tangent, and π sets the height of the whole density of slopes.
Four properties set the Cauchy law apart from the Gaussian:
- No mean: the integral of $\lvert x\rvert f(x)$ diverges
- No variance: the second moment is infinite
- Stable: the average of $n$ independent standard Cauchy variables is again standard Cauchy, so averaging never narrows it
- No central limit theorem: the theorem needs finite variance, so more samples bring no concentration around a centre
Half a century later, a statistician at the Guinness brewery needed a distribution for small samples. William Sealy Gosset published it in 1908 under the pseudonym “Student.” His $t$-distribution with one degree of freedom reduces exactly to the Cauchy, the simplest member of the family and the only one without an average.